NSDI '27
Kuiper: Enterprise Cloud Plug-and-Play Network Management Platform
USENIX 网络系统设计与实现研讨会 (NSDI '27), 2027. 即将发表。
副教授
AI / 网络基础设施测量
AI & Network Infrastructure Measurement
AI / 网络基础设施资源调度
AI & Network Infrastructure Resource Scheduling
AI / 网络基础设施智能运维与安全防护
AI & Network Infrastructure Intelligent Operations & Security
我的研究面向 AI / 网络基础设施,构建 测量、资源调度、智能运维与安全防护 技术,覆盖互联网(BGP、RPKI、DNS、Web PKI)、ISP 与运营商骨干网、FITI / CERNET / CERNET2 国家级试验设施,以及从智算集群到超大规模云与 Serverless 平台的智算 / 数据中心。研究工作分为 三个方向,详见下方 研究方向:
三个方向服务于同一个目标:让 AI / 网络基础设施看得清、调得优、管得好、守得住——从操作系统内核与可编程数据平面,一直延伸到国家级骨干网与智算中心。
我主导了 DeepShield 等项目,在 SIGCOMM、NSDI、CCS、NDSS、CoNEXT、INFOCOM、IEEE/ACM ToN 等国际顶级会议与期刊发表论文近百篇。研究成果已被工业界广泛采用,相关技术深度融入 中国电信骨干网、未来互联网试验设施(FITI)、CERNET / CERNET2 等国家关键网络基础设施,服务于电信运营商、国防及其他关乎国计民生的重要领域。
本人荣获 ACM SIGCSE 中国新星奖,担任 《通信技术》 期刊编委、MDPI Electronics 与 IEEE JSAC 客座编辑,长期为 IEEE/ACM ToN、IEEE TPDS、IEEE TIFS 等期刊审稿;担任 USENIX NSDI、USENIX Security、IEEE INFOCOM、ACM CoNEXT、IEEE ICNP 等国际会议程序委员会委员,并担任 ACM SIGCOMM NGNO 研讨会程序委员会共同主席。研究形成的技术已服务于数亿用户。
“下一代互联网与智算中心,需要 看得清、调得优、管得好、守得住 的基础设施。我们的使命,是构建让这一切成为可能的系统。”
从内核、数据平面到全球路由系统,以线速、零应用改造的方式端到端观测生产基础设施。
零代码分布式追踪
SIGCOMM'23
SIGCOMM'25
ICSE'26;
SRv6 探测与时延诊断
ICNP'25
ToN'26;
可编程交换机流测量
TPDS'22;
Looking Glass 发现与 Web 基础设施可观测
WWW'26;
AS 商业关系推断
ToN'25;
域间路由控制平面与数据平面不一致
ICNP'26;
IPv6 与 IP 地理定位测量
ISCC'23
IFIP Networking'23;
面向数据平面故障的测试报文生成
TPDS'23。
把测量转化为决策,让广域网、数据中心与 Serverless 平台上的带宽与算力高效、抗故障地运转。
跨数据中心广域网流量工程
CoNEXT'21
ToN'22;
网络效用最大化
ICNP'22
ToN'25;
路由代数与故障感知的流量工程
INFOCOM'25
IWQoS'25
CNSM'21;
可编程交换机网内加速
INFOCOM'24
TPDS'22;
Serverless 与云资源管理
TPDS'23
IWQoS'22
ICWS'23;
服务功能链部署与调度
TPDS'26
CNSM'21;
拥塞控制与 Coflow 调度
IWQoS'23
TPDS'19;
企业云即插即用网络管理
NSDI'27。
在配置上线之前完成验证、在故障中快速定位,并在 ISP 规模上发现攻击与入侵。
配置与策略验证
TIFS'24
CoNEXT'25
INFOCOM'26;
可编程交换机在线加密流量入侵检测
SIGCOMM'25
SIGCOMM'26;
可解释、能应对漂移的异常检测
CCS'21
NDSS'23
TIFS'23;
基于溯源图的 APT 检测
TIFS'22
TIFS'25
IEEE Network'26;
日志异常检测
TIFS'21;
Serverless 钱包耗尽攻击检测
CCS'22
ToN'26;
BGP 与 RPKI 路由安全
CCS'26
ICNP'26
CCS'25;
Web PKI / ACME 安全
WWW'25;
大模型辅助的漏洞验证代码生成
电子学报'26。
部署于生产环境的端到端系统——在规模化场景中测量、运维与守护 AI / 网络基础设施。
生产级分布式追踪,跨异构服务重建端到端请求路径,无需修改任何应用代码。双路径 eBPF 内核 + 用户态协议解析实现方法级延迟估计,开销比侵入式基线降低约 10 倍。已部署于多个大规模智算中心集群。
端到端出入口安全防护:链路级流量可视化、实时态势感知和基于 ML 的威胁检测。运行于可编程交换机(P4 / Tofino)、DPU、SmartNIC和 eBPF——实现 Tbps 级线速加密流量分析,同时抵御对抗逃逸和概念漂移。
开源代码、数据集与研究成果,回馈社区。
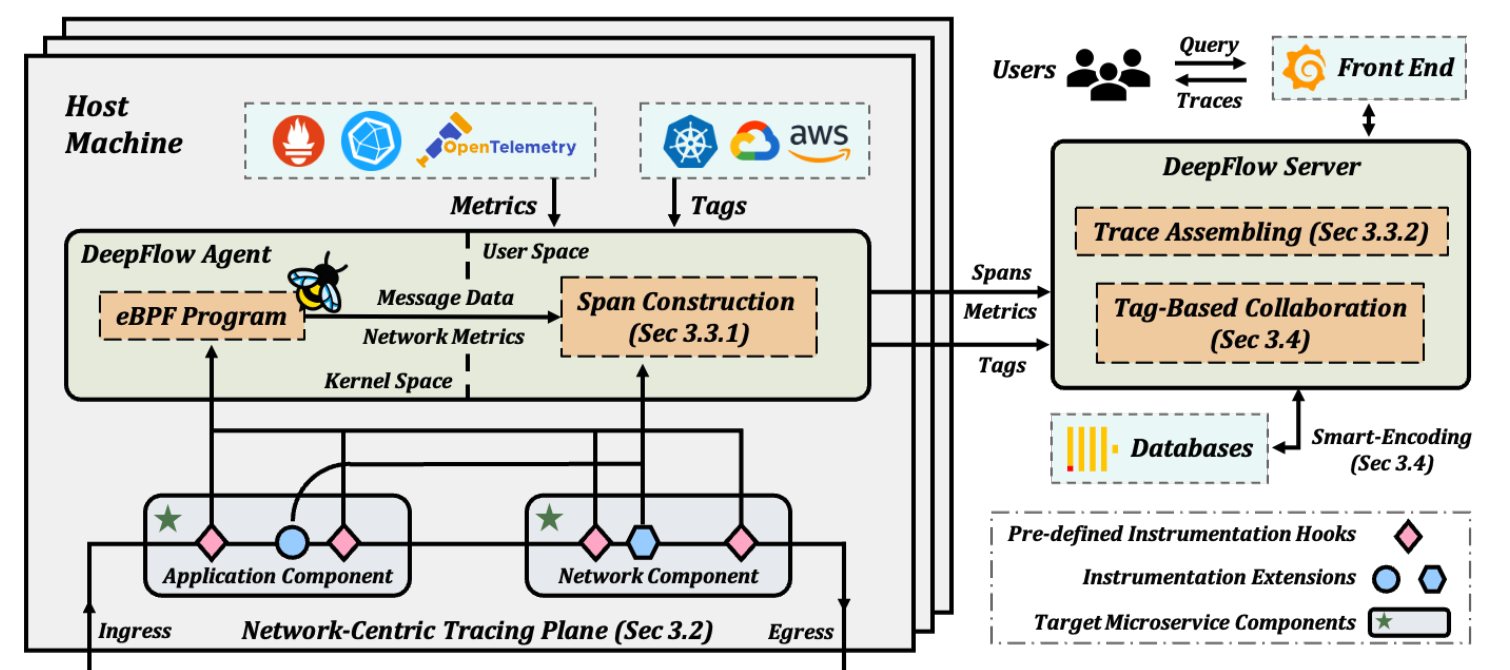
面向云原生与 AI 基础设施的零代码 eBPF 可观测性:以网络为中心的追踪平面跨 Kubernetes、服务网格、Serverless 平台与 LLM / AI 智能体流水线重建端到端因果追踪,并发现性能与安全事件,无需修改任何应用代码。已作为行业事实标准开源(CNCF Sandbox,4k+ ★)。
面向智算中心与大规模微服务部署的分布式应用追踪与故障监控。基于事务的无侵入追踪在高并发下准确率仍 超过 95%,方法级时延估计(ICSE '26)相比 DeepFlow 与 TraceWeaver 将追踪准确率再提升 51%;已被数十家企业用于生产环境的故障诊断与资源优化。
端到端出入口流量监测:链路级可视化、流量态势感知和安全事件检测。同一管线运行于可编程交换机、DPU、SmartNIC和eBPF——依托线速 ML IDS 研究(SIGCOMM '25 P4-IDS, SIGCOMM '26),已在运营商骨干网验证。
面向智算中心的统一智能运维平台,集成故障管理、安全事件响应和配置管理,构建在共享遥测与验证基座之上——依托 SRv6 切片并行探测(ICNP '25, ToN '26)、分布式追踪(SIGCOMM '25)和配置验证工具链。
持续的互联网全域主被动探测,覆盖 IP 空间、路由(BGP / RPKI)和证书(CT 日志 / Web-PKI)——构建可查询的互联网知识库,为下游测量、态势感知和信任验证管线提供支撑。
面向运营和试验网络的静态网络验证与仿真:配置验证器(TIFS '24, INFOCOM '26)、覆盖网集成检验(CoNEXT '25)和定量策略验证,加上 what-if 分析模拟器——通过环境缩减和集成检验扩展到运营商规模。
面向大规模网络诊断的切片并行 SRv6 探测:利用 SRv6 段路由在单轮探测中同时覆盖多条覆盖路径,实现全网格延迟图的 O(1) 轮次。已在国家 FITI 试验设施验证,部署于运营商网络实时瓶颈定位。
研究成果已融入国家级网络基础设施与一线产业产品, 服务电信运营商、教育科研网络、公有云与安全厂商。
线速加密流量异常检测;大规模 WAN 感知与优化。
可编程交换机 IDS 与段路由诊断已部署于国家级下一代互联网试验设施。
面向中国教育与科研计算机网的 DeepFlow 可观测性与路由异常分析。
大规模微服务系统可观测性;联合设计跨数据中心 WAN 流量工程。
面向企业 SD-WAN 产品的应用感知 WAN 传输优化。
安全测试设备与大规模流量分析的关键技术。
* 通讯作者 · † 共同一作 · 下划线 表示指导的学生。 Full list on Google Scholar.
USENIX 网络系统设计与实现研讨会 (NSDI '27), 2027. 即将发表。
ACM 数据通信专业委员会年会 (SIGCOMM '26), pp. 1282–1298, 2026.
In order to provide security connections to the enterprise campus sites, internet service providers are offering comprehensive intrusion detection services at the network layer. However, existing network intrusion detection systems (NIDS) are either ineffective or inefficient for high-speed network protection, especially for encrypted traffic analysis. In this paper, we design and implement SiteGuard, an inline network intrusion detection system with programmable switches specifically developed to protect enterprise campus sites connecting to ISP. SiteGuard proposes a dual-plane feature extraction model to extract extensive traffic features at near line-speed. SiteGuard also proposes a lightweight one-class classification model that trains the best parameters exclusively on benign traffic to identify malicious traffic. In addition, SiteGuard introduces an online update mechanism that aims to dynamically adjust the detection model in response to environmental changes. SiteGuard has been in production for more than three years. Our production and testbed evaluations demonstrate SiteGuard can detect malicious traffic with approximately 90% accuracy in minutes.
ACM 数据通信专业委员会年会 (SIGCOMM '25), pp. 1056–1069, 2025.
As microservices grow in scale and complexity, their operation and debugging become increasingly challenging. Even a single user request can involve interactions across hundreds of components. In such intricate systems, distributed tracing, which tracks the end-to-end execution flow of requests, has become a critical monitoring tool. Among these, non-intrusive tracing frameworks that do not require code modification are particularly valued for their convenience. However, existing non-intrusive solutions either have limited applicability or lack sufficient accuracy under high concurrency. To address these challenges, we propose DeepTrace, a transaction-based, non-intrusive distributed tracing framework designed for microservices. DeepTrace leverages API endpoints and transaction fields embedded within request content to categorize requests into distinct transactions, thereby reducing the likelihood of incorrectly merging traces from different transactions. Compared to state-of-the-art frameworks, DeepTrace maintains an accuracy rate of over 95% even under high concurrency. It has also been adopted by dozens of companies in their production systems for tasks such as failure diagnosis and resource optimization.
@inproceedings{Geng_2025, series={SIGCOMM ’25}, title={Low-Overhead Distributed Application Observation with DeepTrace: Achieving Accurate Tracing in Production Systems}, url={http://dx.doi.org/10.1145/3718958.3750477}, DOI={10.1145/3718958.3750477}, booktitle={Proceedings of the ACM SIGCOMM 2025 Conference}, publisher={ACM}, author={Geng, Yantao and Zhang, Han and Wu, Zhiheng and Li, Yahui and Wang, Jilong and Yin, Xia}, year={2025}, month=Aug, pages={1056–1069}, collection={SIGCOMM ’25} }ACM 数据通信专业委员会年会 (SIGCOMM '25), pp. 1254–1256, 2025.
Attacks against data centers are becoming more common as a result of the fast expansion of applications. In order to keep pace with the growing amount of data centers connected to their networks, internet service providers must offer comprehensive security services. However, existing network intrusion detection systems (NIDS) are either ineffective or inefficient for the high-speed encrypted network traffic. In this paper, we design and implement Mazu, an inline network intrusion detection system with programmable switches specifically developed to protect data centers connecting to the internet service provider. Mazu proposes a dual-plane feature extraction model to extract extensive traffic features at near line-speed. Mazu also proposes a lightweight one-class classification model that trains the best parameters exclusively on benign traffic to identify the malicious traffic. In addition, Mazu introduces an online update mechanism aimed at dynamically adjusting the detection model in response to environmental changes. Mazu has been in production for two years, during which time it has identified over 10 critical attack events and protect more than 10 million servers for two ISPs. Our production and testbed evaluations demonstrate that Mazu can detect malicious traffic entering the data center sites with approximately 90% accuracy within minutes.
@inproceedings{Zhang_2025, series={SIGCOMM ’25}, title={Achieving High-Speed and Robust Encrypted Traffic Anomaly Detection with Programmable Switches}, url={http://dx.doi.org/10.1145/3718958.3750493}, DOI={10.1145/3718958.3750493}, booktitle={Proceedings of the ACM SIGCOMM 2025 Conference}, publisher={ACM}, author={Zhang, Han and Liu, Guyue and Shi, Xingang and Li, Yahui and He, Dongbiao and Wang, Jilong and Wang, Zhiliang and Zhu, Yongqing and Ruan, Ke and Cao, Weihua and Yin, Xia}, year={2025}, month=Aug, pages={1254–1256}, collection={SIGCOMM ’25} }ACM 数据通信专业委员会年会 (SIGCOMM '23), pp. 420–437, 2023.
Microservices are becoming more complicated, posing new challenges for traditional performance monitoring solutions. On the one hand, the rapid evolution of microservices places a significant burden on the utilization and maintenance of existing distributed tracing frameworks. On the other hand, complex infrastructure increases the probability of network performance problems and creates more blind spots on the network side. In this paper, we present DeepFlow, a network-centric distributed tracing framework for troubleshooting microservices. DeepFlow provides out-of-the-box tracing via a network-centric tracing plane and implicit context propagation. In addition, it eliminates blind spots in network infrastructure, captures network metrics in a low-cost way, and enhances correlation between different components and layers. We demonstrate analytically and empirically that DeepFlow is capable of locating microservice performance anomalies with negligible overhead. DeepFlow has already identified over 71 critical performance anomalies for more than 26 companies and has been utilized by hundreds of individual developers. Our production evaluations demonstrate that DeepFlow is able to save users hours of instrumentation efforts and reduce troubleshooting time from several hours to just a few minutes.
@inproceedings{Shen_2023, series={ACM SIGCOMM ’23}, title={Network-Centric Distributed Tracing with DeepFlow: Troubleshooting Your Microservices in Zero Code}, url={http://dx.doi.org/10.1145/3603269.3604823}, DOI={10.1145/3603269.3604823}, booktitle={Proceedings of the ACM SIGCOMM 2023 Conference}, publisher={ACM}, author={Shen, Junxian and Zhang, Han and Xiang, Yang and Shi, Xingang and Li, Xinrui and Shen, Yunxi and Zhang, Zijian and Wu, Yongxiang and Yin, Xia and Wang, Jilong and Xu, Mingwei and Li, Yahui and Yin, Jiping and Song, Jianchang and Li, Zhuofeng and Nie, Runjie}, year={2023}, month=Sept, pages={420–437}, collection={ACM SIGCOMM ’23} }ACM 计算机与通信安全会议 (CCS '22), pp. 2627–2641, 2022.
Serverless computing, or Function-as-a-Service, is gaining continuous popularity due to its pay-as-you-go billing model, flexibility, and low costs. These characteristics, however, bring additional security risks, such as the Denial-of-Wallet (DoW) attack, to serverless tenants. In this paper, we perform a real-world DoW attack on commodity serverless platforms to evaluate its severity. To identify such attacks, we design, implement, and evaluate Gringotts, an accurate, easy-to-use DoW detection system with a negligible performance overhead. Gringotts addresses the information ambiguity inherent in serverless functions by introducing a well-designed performance metrics collection agent. Then, Gringotts uses the Mahalanobis distance to discover anomalies in the distribution of the metrics. We implement Gringotts as a real system and conduct extensive experiments using a testbed to evaluate the performance of Gringotts. Our results indicate that Gringotts has a performance overhead of less than 1.1%, with an average detection delay of 1.86 seconds and an average accuracy of over 95.75%.
@inproceedings{Shen_2022, series={CCS ’22}, title={Gringotts: Fast and Accurate Internal Denial-of-Wallet Detection for Serverless Computing}, url={http://dx.doi.org/10.1145/3548606.3560629}, DOI={10.1145/3548606.3560629}, booktitle={Proceedings of the 2022 ACM SIGSAC Conference on Computer and Communications Security}, publisher={ACM}, author={Shen, Junxian and Zhang, Han and Geng, Yantao and Li, Jiawei and Wang, Jilong and Xu, Mingwei}, year={2022}, month=Nov, pages={2627–2641}, collection={CCS ’22} }ACM CoNEXT '21, 2021.
Inter-DataCenter Wide Area Network (Inter-DC WAN) that connects geographically distributed data centers is becoming one of the most critical network infrastructures. Due to limited bandwidth and inevitable link failures, it is highly challenging to guarantee network availability for services, especially those with stringent bandwidth demands, over inter-DC WAN. We present BATE, a novel Traffic Engineering (TE) framework for bandwidth availability (BA) provision, which aims to ensure that each bandwidth demand must be satisfied with a stipulated probability, when subjected to the network capacity and possible failures of the inter-DC WAN. The three core components of BATE, i.e., admission control, traffic scheduling and failure recovery, are formulated through different mathematical models and theoretically analyzed. They are also extensively compared against state-of-the-art TE schemes, using a testbed as well as real trace driven simulations across different topologies, traffic matrices and failure scenarios. Our evaluations show that, compared with the optimal admission strategy, BATE can speed up the online admission control by 30x at the expense of less than 4% false rejections. On the other hand, compared with the latest TE schemes like FFC and TEAVAR, BATE can meet the bandwidth availability targets for 23%~60% more demands under normal loads, and when network failure causes BA targets violations.
@inproceedings{Zhang_2021, series={CoNEXT ’21}, title={Boosting bandwidth availability over inter-DC WAN}, url={http://dx.doi.org/10.1145/3485983.3494843}, DOI={10.1145/3485983.3494843}, booktitle={Proceedings of the 17th International Conference on emerging Networking EXperiments and Technologies}, publisher={ACM}, author={Zhang, Han and Shi, Xingang and Yin, Xia and Wang, Jilong and Wang, Zhiliang and Guo, Yingya and Lan, Tian}, year={2021}, month=Dec, pages={297–312}, collection={CoNEXT ’21} }ACM / IEEE 国际软件工程会议 (ICSE '26), pp. 1661–1673, 2026.
As the scale and complexity of microservices increase, their operation and debugging become increasingly challenging. A single user request may involve interactions among hundreds of components. In such complex systems, non-intrusive distributed tracing techniques, which require no modification of application code, significantly enhance the convenience of troubleshooting. However, existing non-intrusive tracing frameworks still exhibit critical shortcomings in achieving tracing accuracy: current approaches either rely on specific thread model assumptions, limiting their applicability, or employ incorrectly constructed causal delay distributions to infer request causality, leading to erroneous trace construction. To overcome these limitations, we propose FlowScope, a non-intrusive distributed tracing framework for microservices that optimizes trace reconstruction through method-level delay distribution estimation. This framework estimates the causal delay distribution between requests of different method types via cross-correlation analysis, then uses these delay distributions to accurately evaluate the probability of causal relationships between requests. Subsequently, it efficiently reconstructs traces by incorporating multiple constraints with an iterative algorithm. Our testbed results indicate that FlowScope improves tracing accuracy by 51% compared to state-of-the-art frameworks (e.g., DeepFlow and TraceWeaver) and has been successfully applied in multiple real-world use cases.
ACM Web 会议论文集 (WWW '25), 2025.
The Automatic Certificate Management Environment (ACME) protocol automates the issuance and renewal of secure socket layer certificates, simplifying the management of large-scale certificate deployments. To reduce the load on Certificate Authority (CA) servers, ACME employs a caching mechanism that stores domain validation (DV) results for 30 days. However, this mechanism allows attackers to reuse previously authorized results, potentially bypassing the DV process. In this paper, we introduce the ACME Authz Cache Attack, whereby an attacker can obtain fraudulent certificates without domain control. We demonstrate that even the prominent CA, Let's Encrypt, is vulnerable to this attack. To mitigate this, we propose ACME++, an enhanced protocol that binds the client's IP address and a unique identifier to the ACME account, ensuring secure authorization for each new client and effectively preventing the ACME Authz Cache Attack. Our implementation of ACME++ shows that it introduces little overhead to the CA server.
@inproceedings{Zhang_2025, series={WWW ’25}, title={ACME++: A Secure Authorization Mechanism for ACME Clients in the Web PKI Ecosystem}, url={http://dx.doi.org/10.1145/3696410.3714763}, DOI={10.1145/3696410.3714763}, booktitle={Proceedings of the ACM on Web Conference 2025}, publisher={ACM}, author={Zhang, Tianyu and Zhang, Han and Wei, Yunze and Li, Yahui and Shi, Xingang and Wang, Jilong and Yin, Xia}, year={2025}, month=Apr, pages={1058–1067}, collection={WWW ’25} }ACM Web 会议论文集 (WWW '26), pp. 7576–7587, 2026.
Looking Glass (LG) vantage points (VPs) are valuable for enhancing the observability of distributed web infrastructures. However, their comprehensive discovery faces significant challenges due to the inherent heterogeneity and obscurity of LG services. We present GlassMiner, a novel mining framework that fuses structural and semantic features to discover Internet-wide LG web services and the corresponding VPs. To achieve comprehensive, efficient, and accurate discovery, GlassMiner employs structure-pattern fused clustering and targeted adaptive crawling on heterogeneous LG webpages and integrates large language models for semantic-driven classification. Overall, GlassMiner uncovers 3,867 LG webpages and 7,558 VPs that were previously undocumented in public lists and undetected by prior methods. Compared to state-of-the-art approaches, it represents a 1.82x increase in discovery while operating at 3.43x greater mining efficiency. To demonstrate their value for enhancing web infrastructure observability, we further leverage these newly discovered LGs to investigate routing performance and detours in two large-scale CDNs.
IEEE INFOCOM 2024, pp. 2348–2357, 2024.
In face of packet loss, latency-sensitive multimedia applications cannot afford re-transmission because loss detection and re-transmission could lead to extra latency or otherwise compromised media quality. Alternatively, forward error correction (FEC) ensures reliability by adding redundancy and it is able to achieve lower latency at the cost of bandwidth and computational overheads. We propose to re-locate FEC encoding to hardware that better suits the computational pattern of FEC encoding than CPUs. In this paper, we present NetFEC, an in-network acceleration system that offloads the entire FEC encoding process on the emergent programmable switching ASICs, eliminating all CPU involvement. We design the ghost packet mechanism so that NetFEC can be compatible with important media transport functionalities, including congestion control, pacing and statistics. We integrate NetFEC with WebRTC and conduct extensive experiments with real hardwares. Our evaluations demonstrate that NetFEC is able to eliminate server CPU burden and adds negligible overheads.
@inproceedings{Qiao_2024, title={NetFEC: In-network FEC Encoding Acceleration for Latency-sensitive Multimedia Applications}, url={http://dx.doi.org/10.1109/INFOCOM52122.2024.10621183}, DOI={10.1109/infocom52122.2024.10621183}, booktitle={IEEE INFOCOM 2024 - IEEE Conference on Computer Communications}, publisher={IEEE}, author={Qiao, Yi and Zhang, Han and Wang, Jilong}, year={2024}, month=May, pages={2348–2357} }IEEE 国际网络协议会议 (ICNP '25), pp. 1–12, 2025.
Segment Routing over IPv6 (SRv6) has attracted more attention from network operators. Diagnosing performance bottlenecks for SRv6 tunnels is critical to maintaining network quality. However, SRv6 introduces priority policies, special forms of multipath routing, and SR-based network slicing, all of which make existing methods difficult to apply. In this paper, we present SRmesh, a framework for diagnosing latency bottleneck links specifically tailored for SRv6 tunnel performance analysis. First, we adopt SR-based probing to deterministically control routing paths and ensure that probe packets emulate real production traffic. Second, we employ a latency-based multipath inference to resolve routing ambiguities caused by SR. Third, we introduce a topology-independent progressive diagnosis that incrementally reuses probe results to reduce redundant measurements, optimizing diagnostic overhead for large-scale SRv6 overlay networks. We implement a prototype of SRmesh and conduct extensive evaluations on real network topologies. The results indicate that SRmesh achieves high diagnostic accuracy with up to a 91.9% reduction in probe overhead, demonstrating its practicality and scalability in large-scale SRv6 environments.
IEEE INFOCOM 2026, pp. 1–10.
Verifying network configurations under all possible environments is critical for uncovering latent configuration bugs. However, due to the vastness of the environment space and the limitations of existing approaches, current tools either fail to scale or explore only a tiny fraction of the full environment space, missing many potential issues. In this paper, we show that it is unnecessary to explore the full environment space. Instead, we introduce an effective reduction of the environment space, under which the network preserves all routing and forwarding behaviors exhibited under the full environment space. We develop a theory of network behavior equivalence between the full and effectively reduced environment spaces, and propose an efficient algorithm to compute such an effective reduction. We implement our approach in a tool called Bulwark. Experiments on both real-world and synthetic networks show that Bulwark uncovers numerous new misconfigurations and delivers orders-of-magnitude speedups over state-of-the-art verifiers.
IEEE INFOCOM 2025, pp. 1–10.
The complexity of routing requirements leads to increasingly intricate routing metrics. Existing routing algebra theories have demonstrated that convergent and optimal routing algorithms can be designed only when path metrics satisfy certain properties such as monotonicity and isotonicity. Furthermore, some non-isotonic metrics can be converted into isotonic forms on partial orders through reduction. However, practical scenarios often involve non-commutative algebraic properties, which are overlooked by existing theories. For these problems, there lacks a unified framework to study their solvability, a systematic method for their reduction, and an efficient algorithm to compute optimal routes. In this work, we extend routing algebra to accommodate non-commutative routing problems, propose general reduction methods for them, and explore their solvability. In addition, we design a link state algorithm that converge fast on a reduced partial order. All these discussions are supported by concrete examples, theoretical proofs, and simulations on various network topologies.
ACM CoNEXT 2025.
Overlay/underlay architecture is increasingly prevalent in modern networks but also introduces greater complexity and error-proneness. Existing control plane verifiers for underlay networks face scalability and interpretability challenges when extended to overlay/underlay networks due to methodological limitations. This paper presents MEV, the first control plane verifier designed for overlay/underlay networks. MEV introduces ensemble verification, a novel verification paradigm enabling independent reasoning for behaviors within each routing instance or protocol and forwarding behaviors within each virtual network. We implement and deploy MEV on a real nationwide overlay/underlay network, FITI, where it successfully identifies 22 misconfigurations that could cause isolation and reachability issues. Furthermore, we evaluate MEV against Batfish+ on FITI and a range of synthetic networks with diverse scales, and find that it achieves up to a 102× speedup over Batfish+.
@article{Liu_2025, title={Scalable and Interpretable Overlay Network Checking via Ensemble Verification}, volume={3}, ISSN={2834-5509}, url={http://dx.doi.org/10.1145/3768974}, DOI={10.1145/3768974}, number={CoNEXT4}, journal={Proceedings of the ACM on Networking}, publisher={Association for Computing Machinery (ACM)}, author={Liu, XinZhe and Li, Yahui and Zhang, Han and Yin, Xia and Shi, Xingang and Wang, Zhiliang and Ren, Gang and Wang, Jilong and Yao, Jiangyuan}, year={2025}, month=Nov, pages={1–25} }网络与分布式系统安全研讨会 (NDSS '23), 2023.
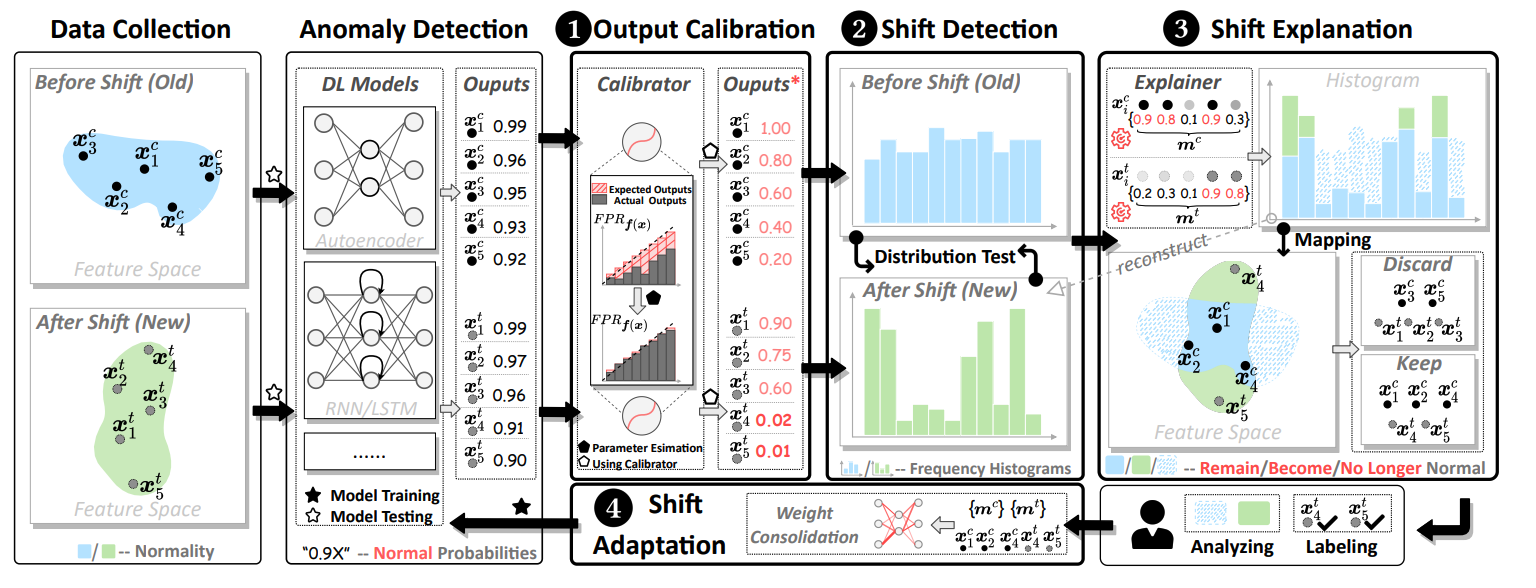
Concept drift is one of the most frustrating challenges for learning-based security applications built on the close-world assumption of identical distribution between training and deployment. Anomaly detection, one of the most important tasks in security domains, is instead immune to the drift of abnormal behavior due to the training without any abnormal data (known as zero-positive), which however comes at the cost of more severe impacts when normality shifts. However, existing studies mainly focus on concept drift of abnormal behaviour and/or supervised learning, leaving the normality shift for zero-positive anomaly detection largely unexplored.
IEEE/ACM 网络汇刊, 2026.
Serverless computing, or Function-as-a-Service, continues to gain popularity due to its pay-as-you-go billing model, flexibility, and cost efficiency. However, these same features introduce significant security risks, such as the Denial-of-Wallet (DoW) attack. In this paper, we conduct real-world DoW attacks on commercial serverless platforms to evaluate their severity. To detect such attacks, we design, implement, and evaluate Clover, an accurate and user-friendly DoW detection system with negligible performance overhead. Clover addresses information ambiguity in serverless environments by deploying a request-oriented metric collection agent. At its core, Clover proposes a workload verification approach to bridge performance metrics and execution duration. Specifically, Clover uses a multivariate linear model to learn the benign relationship between metrics and execution duration, effectively characterizing normal workload behavior. It then continuously monitors runtime workloads by calculating their Mahalanobis distance from this learned benign model. Deviations identified through this distance indicate potential DoW attacks. Implemented as a practical system, Clover introduces performance overhead of less than 3.2%, maintains an average model execution time of only 0.84 microseconds, and achieves an accuracy of 92.7% under the most challenging scenario.
@article{Shen_2026, title={Clover: Workload Verification for Real-Time Detection of Contention-Induced Slowdowns in Serverless Platforms}, volume={34}, ISSN={2998-4157}, url={http://dx.doi.org/10.1109/TON.2026.3680829}, DOI={10.1109/ton.2026.3680829}, journal={IEEE Transactions on Networking}, publisher={Institute of Electrical and Electronics Engineers (IEEE)}, author={Shen, Junxian and Zhang, Han and Lin, Weiwei and Geng, Yantao and Li, Jiawei and Wang, Jilong and Xu, Mingwei}, year={2026}, pages={4700–4715} }IEEE/ACM 网络汇刊, vol. 34, pp. 5588–5600, 2026.
Segment Routing over IPv6 (SRv6) is widely deployed, where operators construct numerous parallel SR-based network slices. An accurate diagnosis of latency bottlenecks in SRv6 tunnels is essential to maintain service-level objectives. However, building a distributed, at-scale probing system is nontrivial: SRv6 priority policies, SR-aware multipath forwarding, and slice isolation collectively invalidate assumptions made by existing diagnostic methods. In this paper, we present SRmesh, a distributed system for diagnosing latency bottleneck links in SRv6 networks. First, we adopt distributed SR-based probing agents to control routing paths and ensure that probe packets emulate per-slice production traffic. Second, we employ a latency-based multipath inference that runs in parallel across slices to resolve SR-induced routing ambiguities. Third, we introduce a slice-parallel progressive diagnosis that incrementally reuses probe results to reduce redundant measurements, optimizing diagnostic overhead for large-scale SRv6 overlay networks. We implement a prototype of SRmesh and conduct extensive evaluations on 247 real network topologies. The results indicate that SRmesh achieves high diagnostic accuracy with a 93.4% reduction in probe overhead, demonstrating its practicality and scalability in large-scale SRv6 environments.
IEEE Transactions on Networking, 2025.
Network utility maximization (NUM) is a fundamental problem for network traffic management and resource allocation. Due to the inherent decentralization and complexity of networks, much of the existing research has focused on developing decentralized algorithms for NUM. However, with the rise of Software-Defined Networking (SDN), especially in cloud networks and inter-datacenter networks managed by large enterprises, there has been growing interest in centralized NUM algorithms. To cope with the large and increasing number of flows in such SDN networks, existing studies on centralized NUM focus on the scalability of the algorithm with respect to the number of flows, but the efficiency is ignored. In this paper, we propose a centralized, efficient and scalable algorithm for the NUM problem. By designing smooth utility and penalty functions, we formulate the NUM problem with a smooth objective function, which enables the use of Nesterov’s accelerated gradient method (AGM). We prove that the proposed method achieves an O(d/t²) convergence rate, demonstrating superior convergence speed with respect to the number of iterations t, and our method is scalable with respect to the number of flows d in the network. Our smooth objective NUM formulation and AGM are effective not only in simple network scenarios with non-prioritized flows routed on one simple paths, but also in more complex and practical scenarios involving prioritized flows routed across multiple complex paths. Experiment results confirm that our method obtains accurate solutions with fewer iterations, and achieves close-to-optimal network utility.
IEEE Transactions on Networking, 2025.
Knowledge of the business relationships between Autonomous Systems (ASes) is the basis for studying many aspects of the Internet. Despite the significant progress achieved by the latest inference algorithms, their inference results still suffer from errors on many special or critical links, thus hindering many relationship-related applications. We take an in-depth analysis on the challenges inherent in inferring AS relationships, including complex routing policies, limited and biased vantage point (VP) coverage, as well as a lack of accurate validation data. To address these challenges, we introduce HELA, a framework for inferring AS relationships with a hybrid of empirical and machine learning algorithms. HELA incorporates an array of grouping, voting, and machine learning algorithms and allows flexible substitution of each. We systematically evaluate various combinations of them to determine the most effective one for HELA. Furthermore, we describe the collection of varied validation datasets, including BGP community and RPSL records from Internet Routing Registries (IRRs), as well as OneStep community. Our up-to-date dataset corrects errors in previous published validation sets, contains 95% more labelled links, and exhibits a closer alignment to actual link distribution. Using routing data and validation datasets composed for each month during 2021∼2023, we access HELA’s superiority in both inference accuracy and stability compared to the state-of-the-art inference algorithms, i.e., AS-Rank, ProbLink, and HELA’s predecessor TopoScope. In particular, HELA achieves up to 2.9× reduction on error rates across overall datasets, up to 2.6× reduction with a 4.5× decrease on standard deviation on incomplete and biased datasets, and up to 1.7× reduction on various sources of validation datasets.
IEEE/ACM 网络汇刊, 2022.
Inter-DataCenter Wide Area Network (Inter-DC WAN) that connects geographically distributed data centers is becoming one of the most critical network infrastructures. Due to limited bandwidth and inevitable link failures, it is highly challenging to guarantee network availability for services, especially those with stringent bandwidth demands, over inter-DC WAN. We present TEDAT, a novel Traffic Engineering (TE) framework for Diverse Availability Targets (DAT), where a Service Level Agreement (SLA) is defined to ensure that each bandwidth demand must be satisfied with a stipulated probability, when subjected to the network capacity and possible failures of the inter-DC WAN. TEDAT has two core components, i.e., traffic scheduling and failure recovery, which are crystalized through different mathematical models and theoretically analyzed. They are also extensively compared against state-of-the-art TE schemes, using a testbed as well as real trace driven simulations across different topologies, traffic matrices and failure scenarios. Our evaluations show that, compared with the optimal admission strategy, TEDAT can speed up the online admission control by 30× at the expense of less than 4% false rejections. On the other hand, compared with the latest TE schemes like FFC and TEAVAR, TEDAT can meet the bandwidth availability SLAs for 23%~60% more demands under normal loads, and when network failure causes SLA violations, it can retain 10%~20% more profit under a pricing and refunding model.
IEEE 并行与分布式系统汇刊, vol. 37, no. 11, pp. 2539–2553, 2026.
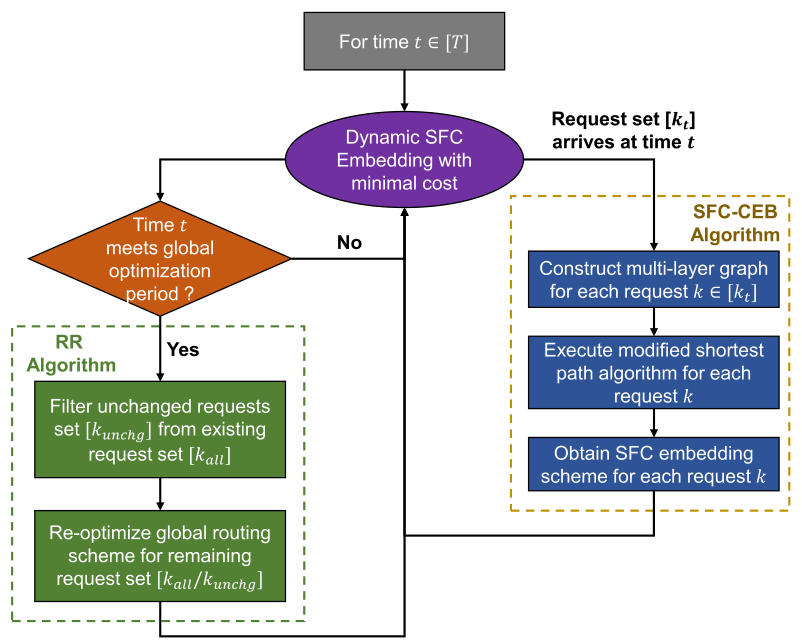
Edge Computing (EC) provides low-latency environment for delay-sensitive network services by deploying limited cloud infrastructure at the edge of the network. Network Function Virtualization (NFV) further enhances flexibility by replacing hardware with Virtual Network Functions (VNFs) that can run on general servers. In NFV, Service Function Chaining (SFC) can provide network services by combining several VNFs in a chain or graph format. NFV therefore allows to deploy network functions in a more flexible and cost-efficient manner, and schedule network resources according to the dynamical variation of network traffic in EC. Optimizing SFC embedding and performance is crucial for service providers to reduce costs and maximize benefits. This paper investigates dynamic SFC embedding in geo-distributed edge clouds for requests with diverse delay requirements. We propose SFCES, a framework integrating a cost-efficient embedding (SFC-CEB) algorithm with a request rerouting (RR) algorithm. SFC-CEB handles initial embedding based on delay needs, while RR periodically re-optimizes routing for active requests. Experimental results show that SFCES reduces embedding cost by 46%∼64% compared to state-of-the-art schemes like RDIP.
IEEE 并行与分布式系统汇刊, vol. 34, no. 8, pp. 2448–2463, 2023.
More and more enterprises deploy applications on Function-as-a-Service (FaaS) platforms to improve resource efficiency and save monetary costs. Network Functions (NFs) suffer from staggered peaks of traffic patterns and could benefit from fine-grained resource multiplexing in FaaS platform. However, naively exploring existing FaaS platforms to support NFs can introduce significant performance overheads in three aspects, including slow instance startup, remote state access for NFs, and costly packet delivery between NFs. To address these problems, we propose Serpens, a high performance FaaS platform for NFs. First, Serpens proposes a reusable NF runtime design to slash instance startup overhead. Second, Serpens designs a novel state management mechanism to support local state access. Third, Serpens introduces an advanced service chaining approach to avoid extra packet delivery. Besides, Serpens designs an NF scaling mechanism to minimize performance fluctuation. We have implemented a prototype of Serpens and conducted comprehensive experiments. Compared with the NFs and Service Function Chains (SFCs) that run on existing FaaS platforms, Serpens can improve the throughput by more than 10× and reduce the latency by more than 90%.
IEEE 并行与分布式系统汇刊, vol. 34, no. 4, pp. 1362–1375, 2023.
The correctness and reliability of modern networks are often the greatest concerns. A myriad network events like software update, device crash and resource exhaustion, inevitably lead to liveness errors on data plane. This paper focuses on fault detection of the network data plane using test packets. Existing test packet generation techniques are limited in two aspects: i) it is difficult to collect the input data plane snapshot through SNMP or terminals ii) it may rise false negatives due to inconsistent snapshot. In this paper, we propose a new framework, SWIFT, that automatically generates test packets with network configurations. SWIFT minimizes the number of test packets by allowing a packet to go through multiple links or interfaces. For network updates, SWIFT updates test packets in an incremental way to revalidate the network. We evaluate its performance using hundreds of benchmark network configurations. The results show that it takes few seconds to generate test packets to exercise all links and interfaces, and updates the test packets in few seconds for configuration changes. We also deployed a SWIFT prototype in a university network, and successfully detected many network outages.
IEEE 并行与分布式系统汇刊, vol. 33, no. 10, pp. 2571–2583, 2022.
In distributed storage systems, Erasure Coding (EC) is a crucial technology to enable high data availability. By downloading parity data from survived machines, EC can reconstruct lost data with much lower storage overheads than data replication. However, this reduction in storage cost comes at the expense of extra performance problems: low reconstruction rate, high degraded read latency, and high host CPU utilization. Our analysis shows that these performance problems are deeply rooted in the host-based EC processing. To resolve these problems, we present NetEC, an in-network accelerating framework that fully offloads EC to the new generation programmable switching ASICs. We propose Explicit Buffer Size Notification (EBSN) to constrain decoding buffer usage, and design an on-switch one-to-many TCP proxy to integrate EBSN with TCP. We also design two parallel Galois Field (GF) offloading methods---table lookup and bitmatrix methods---to maximize parsable bytes. We implement NetEC on programmable switches and integrate it with HDFS. Extensive evaluations show that NetEC improves the reconstruction rate by 2.7x-6.8x, reduces the degraded read latency significantly, and removes the host CPU overhead completely. We also emulate multi-rack scenarios and show that NetEC is able to support ~GB/s reconstruction rate and tens of concurrent tasks.
IEEE 并行与分布式系统汇刊, vol. 33, no. 5, pp. 1069–1083, 2022.
Traditional tools like NetFlow face great challenges as both the speed and the complexity of the network traffic increase. To keep the pace up, we propose HashFlow for more efficient and accurate collection of flow records. HashFlow keeps large flows in its main flow table and uses an ancillary table to summarize the other flows when the main table is full. With our flow collision resolution and flow record promotion schemes, a flow in the ancillary table is promoted back to the main flow table with a guaranteed probability when it becomes large enough. These operations can be performed highly efficiently, so HashFlow can keep up with ultra-high traffic speed. We implement HashFlow in a Tofino switch, and using traces from different operational networks, we compare its performance against some state-of-the-art flow measurement algorithms. Our experiments show that, for various types of traffic analysis applications, HashFlow consistently demonstrates clearly better performance than its competitors. For example, the performance of HashFlow in flow size estimation, flow size distribution estimation and heavy hitter detection is up to 21, 60 and 35 percent better than those of the best competitors respectively, and these merits of HashFlow come with almost no degradation of throughput.
IEEE 信息取证与安全汇刊, 2025.
Critical devices on the Internet are frequently targeted by skilled and advanced network attackers. These attackers often orchestrate complex and persistent intrusion campaigns, which involve multiple stages of attacks. In the context of host-based threat detection, the reconstruction of the entire attack scenario is crucial for tracing threats and fixing system vulnerabilities. Prior anomaly-based studies lack the capability to interpret the attack scenario, while rule-based approaches struggle with detecting novel attack patterns. We introduce eaGle, an end-to-end framework that takes original host-based data as input and reconstructs the potential attack scenario as output. It leverages an anomaly-based algorithm and a fine-grained misuse detection module to assign anomalous scores to host data, constructs the potential attack scenario using a novel anomalous subtree detection algorithm, and generates the interpretable attack scenario graph through a coarse-grained rule matching method. We assess the performance of eaGle using three attack scenarios from the DARPA TC dataset and three deployment scenarios. The results demonstrate that eaGle can effectively uncover the hidden attack scenario within the host data and outperforms three state-of-the-art attack scenario reconstruction systems.
IEEE 信息取证与安全汇刊, vol. 19, pp. 10099–10113, 2024.
Network managers configure networks to enforce various high-level policies, and to respond to the wide range of network events (e.g., attacks, intrusions, malicious route announcements from neighbors) that may occur. It is incredibly difficult to specify these high-level policies in terms of distributed low-level configuration. These high-level policies hold only if the distributed configurations are well equipped to react to unsafe and unreliable environments (e.g., malicious route announcements, unsafe components and devices). Therefore, it is important to proactively verify whether network policies hold across continually changing environments in terms of current network configurations. State-of-the-art policy verification techniques are limited because they can check only the Boolean policies (e.g., forwarding reachability, waypoint or blackhole-freeness). However, many policy violations express themselves in quantitative ways (e.g., a link becomes overloaded). In this paper, we propose quantitative network verification (QNV) analyzing the quantitative policies of networks across unsafe and unreliable environments. QNV translates network configurations into a symbolic simulation model that captures the stable states to which the network forwarding will converge as a result of interactions between routing protocols. It then generates a logical formula matrix that describes network forwarding in the event of failures and verifies quantitative policies based on the formula matrix. We implement QNV and evaluate it on realistic and synthetic configurations. Our evaluation shows that QNV can precisely verify quantitative policies in only a few minutes, even in large networks.
IEEE 信息取证与安全汇刊, vol. 18, pp. 2076–2090, 2023.
Software Defined Network (SDN) has been widely used in modern network architecture. The SD-WAN is considered as a technology that has a potential to revolutionize the WAN service usage by utilizing the SDN philosophy. Attacks within SD-WAN can affect the network and block the entire services. In this paper, we propose a machine learning based anomalous traffic detection framework named OADSD over SD-WAN that can achieve task independently and has the ability of adapting to the environment. The OADSD adopts Distributed Dynamic Feature Extraction (DDFE) to extract representative features directly from the raw traffic, and proposes the On-demand Evolving Isolation Forest (OEIF) to make the system adapt to an environment. We provide a theoretical analysis of the performance of the OADSD. We also conduct comprehensive experiments to evaluate the performance of the OADSD with real world public datasets as well as a small real testbed. Our experiments under real world public datasets show that, the OADSD can accurately detect various kinds of attacks with a high performance. Compared with the state-of-the-art systems, the OADSD can achieve up to 60% accuracy improvement.
IEEE 信息取证与安全汇刊, vol. 18, pp. 1610–1624, 2023.
The hierarchical network is the more effective platform, which provides multiple channels for various worm propagation. Thus, emerging worms can infect vulnerable hosts by scanning strategy and social media. However, the spread of scan-based worm is restrained due to uneven distribution of vulnerable hosts and NAT (Network Address Translation) technique. Meanwhile, topological dependency dictates to topology-based worm only infecting those hosts in social networks. To avoid their respective disadvantages, modern hybrid worm, which combines the above two propagation mechanisms, can implement efficient IP-address scanning by enhanced combination-scanning strategy, and spread more aggressively in social networks using enhanced reinfection mechanism. This paper presents a Hierarchical-Stochastic Propagation model to understand hybrid worm propagation. Inspired by hybrid worm, we design a new vaccine based on the Hierarchical-Measure Immunization strategy. For physical networking layer, we can estimate vulnerable-host distribution to find vulnerable hosts effectively through Maximum Likelihood estimation. For social networking layer, we use a novel propagation centrality measure to discover vital social nodes accurately. The experimental results show that our model can characterize the propagation mechanism of hybrid worms more comprehensively, and greatly outperforms state of the art models in terms of estimation accuracy. Meanwhile, our strategy is more effective to restrain the hybrid worm from spreading in networks.
IEEE 信息取证与安全汇刊, vol. 17, pp. 3972–3987, 2022.
Host-based threats such as Program Attack, Malware Implantation, and Advanced Persistent Threats (APT), are commonly adopted by modern attackers. Recent studies propose leveraging the rich contextual information in data provenance to detect threats in a host. Data provenance is a directed acyclic graph constructed from system audit data. Nodes in a provenance graph represent system entities (e.g., processes and files) and edges represent system calls in the direction of information flow. However, previous studies, which extract features of the provenance graph, are not sensitive to the small quantity of threat-related entities and thus result in low performance when hunting stealthy threats. We present THREATRACE, an anomaly-based detector that detects host-based threats at system entity level without prior knowledge of attack patterns. We tailor GraphSAGE, an inductive graph neural network, to learn every benign entity’s role in a provenance graph. THREATRACE is a real-time system, which is scalable of monitoring a long-term running host and capable of detecting host-based intrusion in their early phase. We evaluate THREATRACE on five public datasets. The results show that THREATRACE outperforms seven state-of-the-art host intrusion detection systems.
IEEE 信息取证与安全汇刊, vol. 16, pp. 2300–2311, 2021.
Cloud technology has brought great convenience to enterprises as well as customers. System logs record notable events and are becoming valuable resources to track and investigate system status. Detecting anomaly from logs as fast as possible can improve the quality of service significantly. Although many machine learning algorithms (e.g., SVM, Logistic Regression) have high detection accuracy, we find that they assume data are clean and might have high training time. Facing these challenges, in this paper, we propose Robust Online Evolving Anomaly Detection (ROEAD) framework which adopts Robust Feature Extractor (RFE) to remove the effects of noise and Online Evolving Anomaly Detection (OEAD) to dynamic update parameters. We propose Online Evolving SVM (OES) algorithm as the example of online anomaly detection methods. We analyze the performance of OES in theory and prove the performance difference between OES and the best hypothesis tends to zero as time goes infinity. We compare the performance of ROEAD against state-of-the-art anomaly detection algorithms using public log datasets. The results demonstrate that ROEAD is able to remove the effects of noise and OES can improve the detection accuracy by more than 40%.
IEEE 国际网络协议会议 (ICNP '22), 2022.
Network utility maximization (NUM) is a well-studied problem for network traffic management and resource allocation. Because of the inherent decentralization and complexity of networks, most researches develop decentralized NUM algorithms. In recent years, the Software Defined Networking (SDN) architecture has been widely used, especially in cloud networks and inter-datacenter networks managed by large enterprises, promoting the design of centralized NUM algorithms. To cope with the large and increasing number of flows in such SDN networks, existing researches about centralized NUM focus on the scalability of the algorithm with respect to the number of flows, however the efficiency is ignored. In this paper, we focus on the SDN scenario, and derive a centralized, efficient and scalable algorithm for the NUM problem. By the designing of a smooth utility function and a smooth penalty function, we formulate the NUM problem with a smooth objective function, which enables the use of Nesterov's accelerated gradient method. We prove that the proposed method has O(d/t²) convergence rate, which is the fastest with respect to the number of iterations t, and our method is scalable with respect to the number of flows d in the network. Experiments show that our method obtains accurate solutions with less iterations, and achieves close-to-optimal network utility.
ACM 计算机与通信安全会议 (CCS '21), 2021.
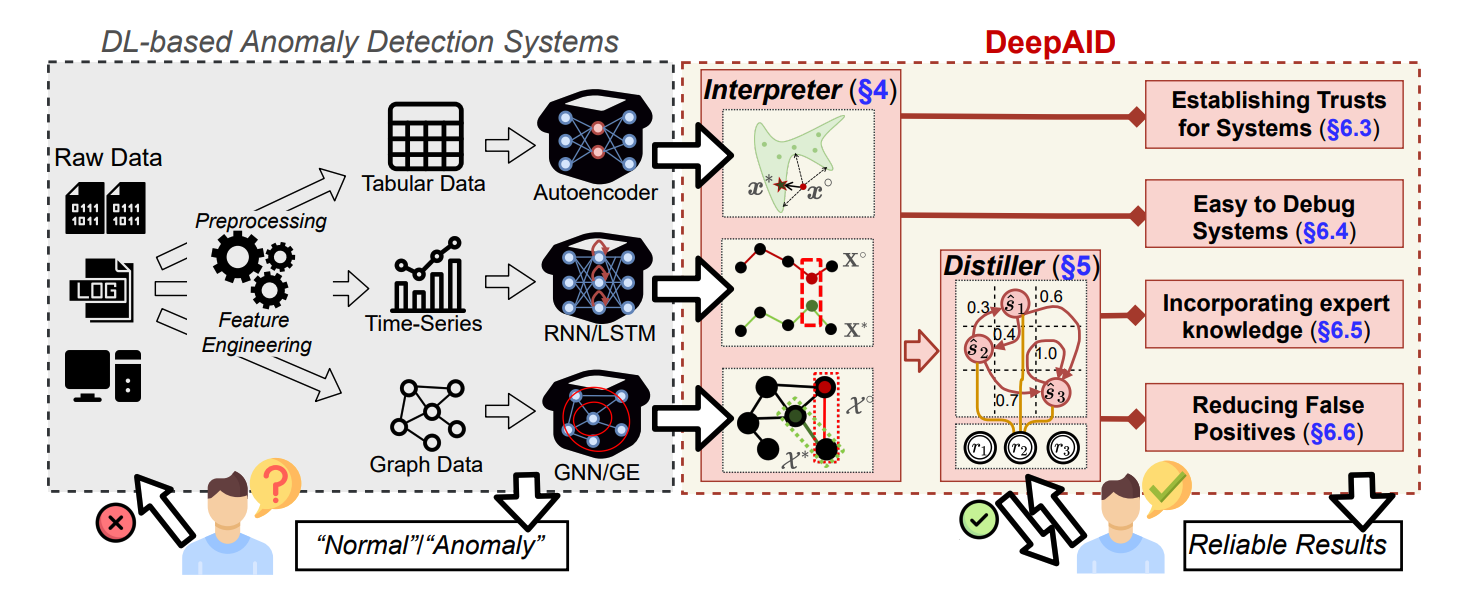
Unsupervised Deep Learning (DL) techniques have been widely used in various security-related anomaly detection applications, owing to the great promise of being able to detect unforeseen threats and superior performance provided by Deep Neural Networks (DNN). However, the lack of interpretability creates key barriers to the adoption of DL models in practice. Unfortunately, existing interpretation approaches are proposed for supervised learning models and/or non-security domains, which are unadaptable for unsupervised DL models and fail to satisfy special requirements in security domains. In this paper, we propose DeepAID, a general framework aiming to (1) interpret DL-based anomaly detection systems in security domains, and (2) improve the practicality of these systems based on the interpretations. We first propose a novel interpretation method for unsupervised DNNs by formulating and solving well-designed optimization problems with special constraints for security domains. Then, we provide several applications based on our Interpreter as well as a model-based extension Distiller to improve security systems by solving domain-specific problems. We apply DeepAID over three types of security-related anomaly detection systems and extensively evaluate our Interpreter with representative prior works. Experimental results show that DeepAID can provide high-quality interpretations for unsupervised DL models while meeting the special requirements of security domains. We also provide several use cases to show that DeepAID can help security operators to understand model decisions, diagnose system mistakes, give feedback to models, and reduce false positives.
@inproceedings{Han_2021, series={CCS ’21}, title={DeepAID: Interpreting and Improving Deep Learning-based Anomaly Detection in Security Applications}, url={http://dx.doi.org/10.1145/3460120.3484589}, DOI={10.1145/3460120.3484589}, booktitle={Proceedings of the 2021 ACM SIGSAC Conference on Computer and Communications Security}, publisher={ACM}, author={Han, Dongqi and Wang, Zhiliang and Chen, Wenqi and Zhong, Ying and Wang, Su and Zhang, Han and Yang, Jiahai and Shi, Xingang and Yin, Xia}, year={2021}, month=Nov, pages={3197–3217}, collection={CCS ’21} }